

AI Data Poisoning: Detection, Risks and Prevention Strategies
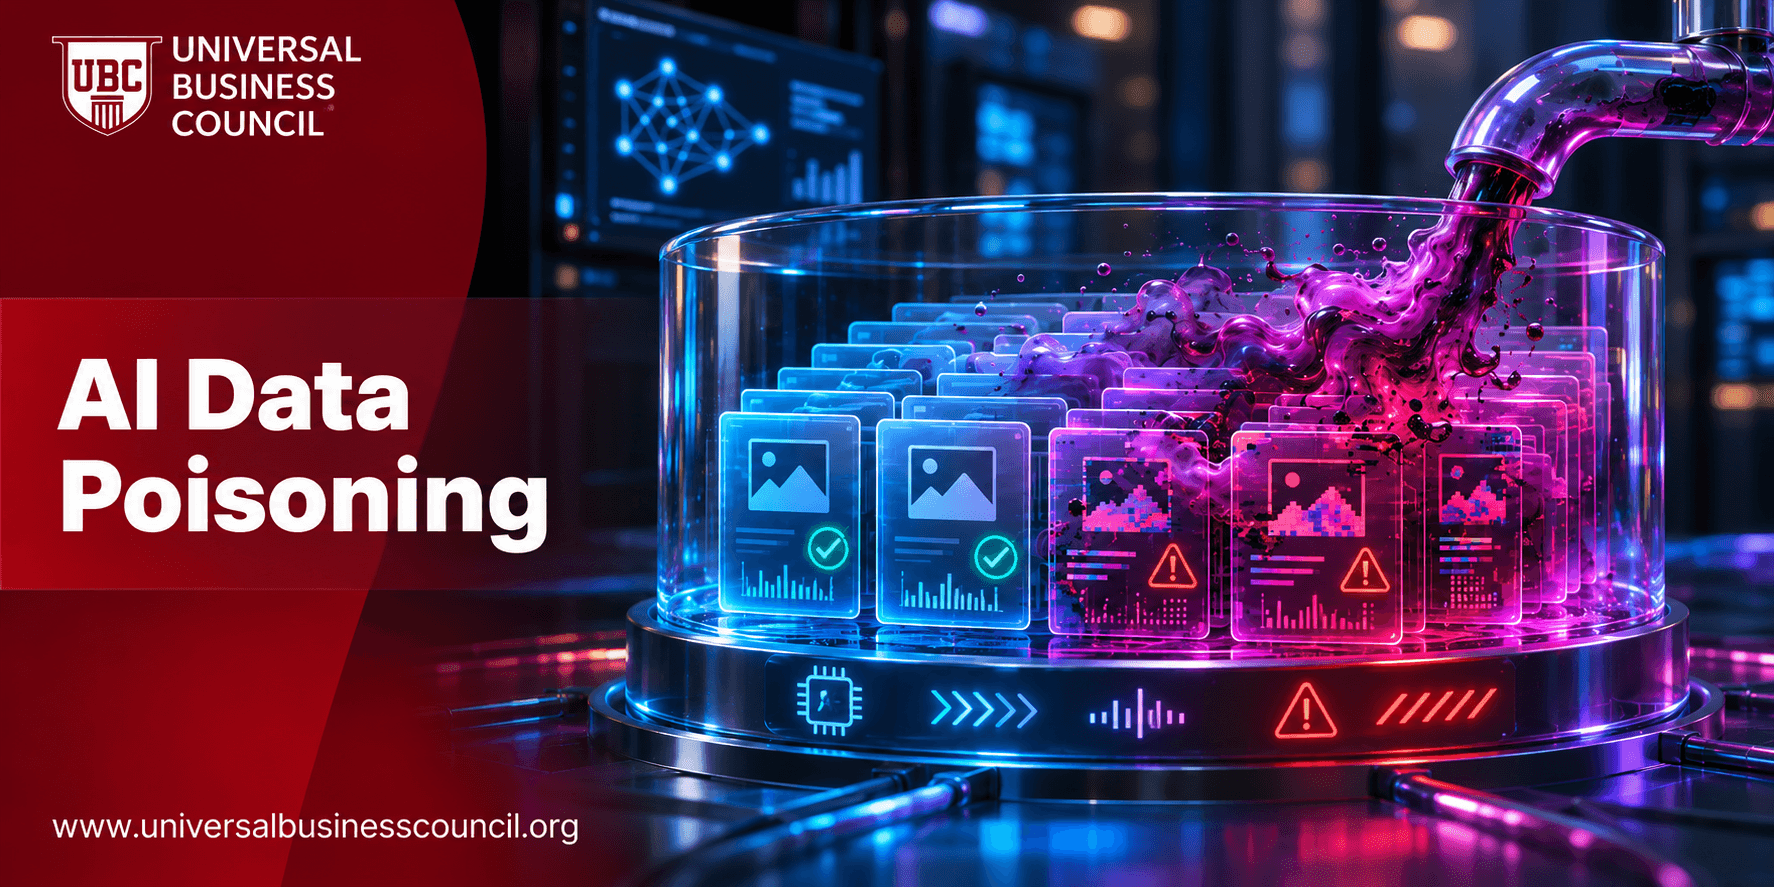
Every model reflects the data it was trained on, which means whoever can influence that data can influence the model. Data poisoning exploits this dependency. A small amount of corrupted or malicious data, placed in the right spot, can quietly skew a model's behavior or install a hidden trigger that waits for the right input.
This guide explains what AI data poisoning is, the main types, the risks to organizations, how to detect it and how to prevent it. Readers who want a broader grounding in responsible AI may also explore the Certified Responsible AI Expert certification from Universal Business Council.

What Is AI Data Poisoning?
AI data poisoning is an attack in which an adversary manipulates the data used to train, fine-tune or update a model, in order to degrade its performance, bias its outputs or implant behavior the attacker can later exploit. It belongs to the family of adversarial machine learning attacks described in NIST's taxonomy and in MITRE ATLAS, and it features in the OWASP list of risks for language model applications.
Poisoning is dangerous because it happens upstream. Once corrupted data is baked into a model, the flaw can be hard to find and expensive to undo, since retraining may be needed. Modern pipelines make exposure easy to create: models learn from web-scale scraped data, third-party datasets, user feedback, crowd-sourced labels and continuously updated sources.
Types of Data Poisoning
Availability Attacks
These aim to reduce overall model quality, making it less accurate or reliable. The attacker adds noisy, mislabeled or misleading data so the model performs poorly across the board. The goal might be sabotage, or damage to a competitor's product.
Targeted Attacks
Here the attacker wants specific wrong outputs for particular inputs, such as causing a fraud model to approve certain transactions or a classifier to mislabel one category, while leaving general performance intact so the attack goes unnoticed.
Backdoor Attacks
A backdoor plants a hidden trigger, such as a pattern, phrase or token. The model behaves normally until the trigger appears, then produces the attacker's chosen result. Backdoors are hard to spot in standard testing because average accuracy stays high.
Other Forms
Label flipping: changing labels to the wrong class
Clean-label attacks: poisoned examples that look correctly labeled to human reviewers
Feedback poisoning: manipulating ratings, reports or user interactions that feed continuous learning
Retrieval and knowledge base poisoning: inserting malicious content into documents that RAG systems retrieve
Fine-tuning and supply chain poisoning: compromised pretrained models or datasets from public repositories
Risks to Organizations
The consequences depend on the use case. A poisoned medical model could suggest harmful actions, a poisoned fraud model could miss attacks, a poisoned hiring model could produce discriminatory outcomes and a poisoned chatbot could spread falsehoods or leak data. Beyond immediate errors, organizations face financial loss, regulatory scrutiny, reputational damage and expensive remediation.
Regulation and standards push organizations to address this risk. The EU AI Act expects high-risk systems to be resilient against attempts to alter their use or performance by manipulating training data, and frameworks such as the NIST AI RMF and ISO/IEC 42001 call for data governance and security controls.
How to Detect Data Poisoning
Detection is challenging, and no method catches everything. Layering techniques improves the odds.
Data validation and profiling: check distributions, duplicates, outliers, label consistency and unusual clusters before training
Source and provenance checks: verify where data came from and who changed it
Anomaly and influence analysis: flag training samples that have unusually strong effects on model behavior
Model testing: evaluate on trusted, held-out test sets, including targeted cases and subgroup checks
Backdoor scanning: use tools that search for hidden triggers and abnormal activation patterns
Monitoring after release: watch for sudden performance shifts, odd outputs and drift
Practitioners who run these checks use scripting and statistics heavily, and short tech certifications can help governance and security staff understand the tooling.
Prevention Strategies
Secure the Data Pipeline
Control who can add or change data. Use access controls, authentication, change logs and versioning. Hash and sign datasets so tampering is detectable, and store lineage records showing every transformation. Separate environments for collection, labeling, training and production reduce the chance of unauthorized changes. Tamper-evident logging approaches, including some based on distributed ledgers, are an active area of interest, and Deep Tech Certifications offer background on those technologies.
Vet Sources and Vendors
Prefer trusted, documented sources and request datasheets for datasets
Scan and review third-party datasets and pretrained models before use
Include security and notification terms in vendor contracts
Limit reliance on unverified scraped or user-submitted data for high-risk systems
Strengthen Training and Labeling
Use multiple labelers and quality checks, spot-audit samples, and apply robust training methods that reduce sensitivity to outliers. For continuous learning systems, rate-limit and filter feedback, and add human review before new data enters training.
Protect People and Processes
Insiders can also poison data, so apply least privilege, separation of duties and monitoring. Many organizations verify credentials and background for staff with access to training pipelines, and HireValid can support that screening.
Responding to Suspected Poisoning
Have a plan. Isolate the affected model or data, preserve logs for investigation, identify the entry point and scope using lineage records, retrain or roll back to a clean version, notify stakeholders as required and document lessons learned. Include poisoning scenarios in your AI incident response playbook and rehearse them.
When incidents become public, clear and honest communication matters. A Digital Marketing Course can help communications teams prepare accurate messaging.
Conclusion
Data poisoning attacks the foundation of AI, the training data. Defend by securing the pipeline, vetting sources, validating and monitoring data and models, limiting access and preparing a response plan. The FAQs below answer common questions.
Frequently Asked Questions
What is AI data poisoning?
Manipulating training or fine-tuning data to harm or control a model's behavior.
Why is poisoning hard to detect?
Small changes can hide inside large datasets while average accuracy stays high.
What is a backdoor attack?
Poisoning that plants a hidden trigger causing specific model behavior.
What is label flipping?
Changing training labels to incorrect classes.
What is a clean-label attack?
Poisoned samples that appear correctly labeled to reviewers.
Can RAG systems be poisoned?
Yes, by inserting malicious content into retrieved documents.
Can user feedback poison a model?
Yes, if feedback feeds continuous learning without filtering.
Who might carry out poisoning?
External attackers, competitors, malicious insiders or compromised vendors.
What risks does it create?
Wrong decisions, bias, data leaks, financial loss and reputational harm.
How can poisoning be detected?
Data profiling, provenance checks, anomaly detection, testing and monitoring.
What is data provenance?
A record of where data originated and how it changed.
How does hashing help?
It makes dataset tampering detectable.
Should third-party models be trusted?
They should be reviewed and tested like third-party code.
How do labeling controls help?
Multiple labelers and audits reduce the chance of bad labels entering training.
Does the EU AI Act mention poisoning?
It expects high-risk systems to resist manipulation of training data.
What is least privilege for data?
Giving people only the data access their role requires.
What do you do if poisoning is suspected?
Isolate, investigate with lineage records, retrain or roll back and document.
Can a poisoned model be fixed?
Often it requires retraining on clean data or rolling back to a trusted version.
How is it different from prompt injection?
Poisoning corrupts training data, while prompt injection manipulates inputs at runtime.
Where should teams start?
By securing and documenting their data pipeline and sources.
Related Articles
View All
Artificial Intelligence
Prompt Injection Risks in AI Systems: Prevention and Mitigation
Learn how prompt injection attacks exploit vulnerabilities in AI systems to manipulate outputs, expose sensitive information, or trigger unauthorized actions. Explore common attack methods, real-world risks, and practical prevention and mitigation strategies to strengthen AI security and protect applications powered by large language models.
Artificial Intelligence
Data Privacy in Artificial Intelligence: Risks, Controls and Best Practices
Explore the key data privacy risks associated with artificial intelligence and how organizations can address them. Learn about sensitive data exposure, unauthorized access, consent, data protection controls, and best practices for safeguarding personal information throughout the AI lifecycle.
Artificial Intelligence
Deepfakes and Synthetic Media: Responsible AI Detection and Prevention
Understand what deepfakes and synthetic media are and explore how responsible AI can help detect and prevent their misuse. Learn about detection techniques, ethical challenges, digital authenticity, and practical strategies for reducing misinformation, protecting privacy, and promoting responsible AI use.
Trending Articles
The Role of Blockchain in Ethical AI Development
How blockchain technology is being used to promote transparency and accountability in artificial intelligence systems.
AWS Career Roadmap
A step-by-step guide to building a successful career in Amazon Web Services cloud computing.
Top 5 DeFi Platforms
Explore the leading decentralized finance platforms and what makes each one unique in the evolving DeFi landscape.