

Federated Learning and Responsible AI: Benefits, Risks and Limitations
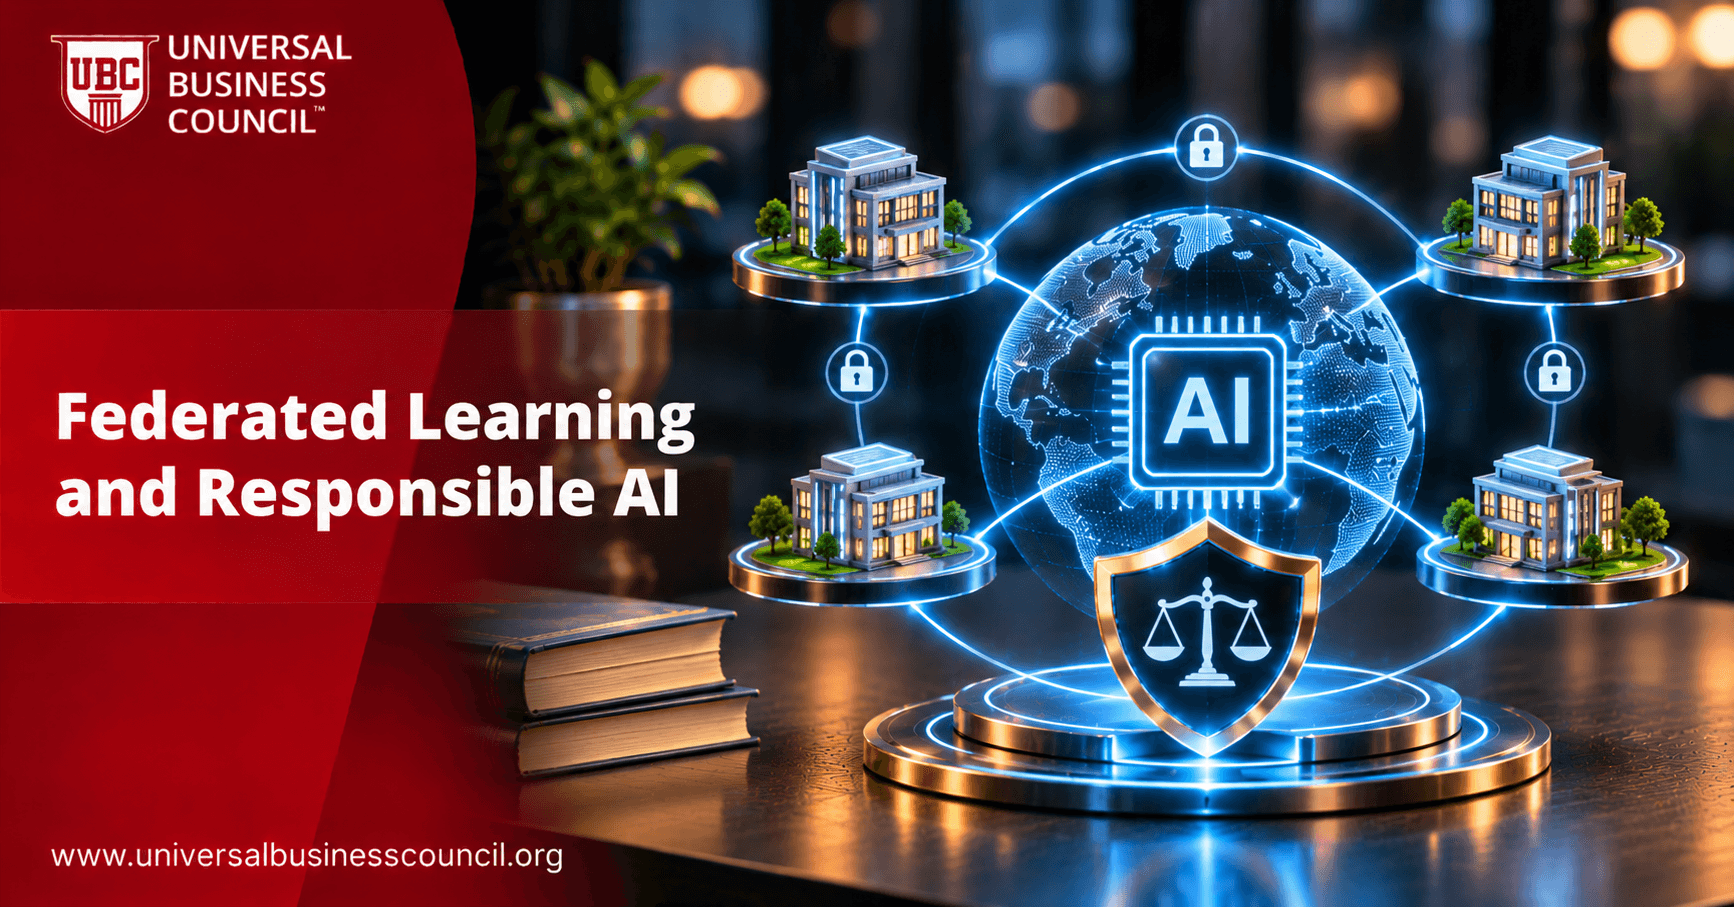
Moving data is often the hardest part of building AI. Privacy law, contracts, competition and sheer volume can make it impossible to pool records in one place. Federated learning takes a different route: leave the data where it is and bring the training to it.
This guide explains how federated learning works, why it appeals to responsible AI teams, where it falls short and how to govern it. Professionals who want wider training on responsible AI may also explore the Certified Responsible AI Expert certification from Universal Business Council.

What Is Federated Learning?
Federated learning is a machine learning approach in which a shared model is trained across many devices or organizations, each holding its own local data, without that data being sent to a central server. Each participant trains the model locally, then shares only model updates, such as weights or gradients. A central server (or a peer network) combines the updates into an improved global model, and the cycle repeats.
The approach was popularized by researchers at Google around 2016 for improving mobile keyboard predictions without uploading what people type. It has since spread to healthcare, finance and industrial settings.
Two Common Settings
Cross-device: millions of phones or sensors, each with small amounts of data, participating intermittently
Cross-silo: a handful of organizations, such as hospitals or banks, each with large datasets and reliable infrastructure
Federated learning can also be horizontal, where parties hold different records with the same features, or vertical, where parties hold different features about the same people.
Benefits for Responsible AI
Privacy and Data Minimization
Because raw data stays local, exposure and breach risk fall, and the approach fits the principle of data minimization found in laws such as the GDPR. It can make it feasible to learn from data that could not legally or practically be centralized, such as patient records across hospitals or regions with different data residency rules.
Better Data Diversity
Access to more varied data can improve model performance and generalization, which can reduce bias that arises from narrow, single-source datasets. A diagnostic model trained across many hospitals may handle more patient populations than one trained at a single site.
Collaboration Without Surrendering Control
Organizations keep ownership of their data and can collaborate even where they compete or distrust one another. This supports industry-wide efforts such as fraud detection and rare-disease research.
Risks and Limitations
Federated learning is often described as private by design, but that overstates it. Several risks need attention.
Privacy Leakage Through Updates
Model updates can reveal information about local data. Researchers have shown gradient inversion and membership inference attacks that recover or detect training records from updates. Protection usually requires extra measures such as secure aggregation, differential privacy and encryption.
Security Threats
Poisoning: a malicious participant sends manipulated updates to degrade the model or plant a backdoor
Free riding or fake participants: contributors that take the benefit without real contribution
Compromised server: a central aggregator that sees updates can become a target
Fairness and Data Heterogeneity
Data across participants is often not identically distributed. Some groups or sites may dominate, which can produce a global model that works well for some and poorly for others. Without testing across participants and subgroups, federated learning can hide bias rather than remove it.
Operational and Technical Challenges
Communication costs, unreliable devices, system heterogeneity, debugging difficulty and limited visibility into local data make federated systems harder to build and maintain than centralized ones. It can also be difficult to explain or audit a model when no one can inspect the full training data.
Governing Federated Learning Responsibly
Define the purpose and legal basis: federated learning does not remove the need for lawful grounds, consent where required and clear purpose limits
Establish a collaboration agreement: cover data ownership, permitted uses, liability, model ownership, security standards and exit terms
Combine privacy techniques: use secure aggregation and differential privacy and set privacy budgets deliberately
Vet participants: authenticate contributors, verify their security posture and monitor for abnormal updates
Test fairness across sites and groups: report results per participant and per subgroup
Document: record architecture, aggregation method, privacy parameters, data descriptions and known limits in model cards and datasheets
Monitor and respond: track performance, drift and security incidents, and plan for removing a participant
Running such programs requires experienced people in machine learning, security and privacy. Organizations often verify credentials and experience when hiring for these roles, and HireValid can help confirm them. Governance staff who oversee federated projects also gain from basic technical literacy, and short tech certifications can help them follow how training pipelines work.
Use Cases
In healthcare, hospitals train imaging and prediction models together without sharing patient files. In finance, banks collaborate on fraud and anti-money-laundering models. Telecom and consumer technology firms improve on-device features such as text prediction and voice recognition. Industrial firms combine sensor data from factories or fleets, and public bodies explore it for sensitive statistics. Federated approaches also intersect with decentralized technologies, and Deep Tech Certifications offer useful background on those connections.
Communicating About Federated Learning
Because the technique is often marketed as private by default, be careful with public claims. Say what is protected and what is not, and avoid promising absolute privacy. A Digital Marketing Course can help teams explain privacy features clearly and honestly.
Conclusion
Federated learning allows organizations to train shared models without centralizing sensitive data, supporting privacy, collaboration and data diversity. But it is not a complete solution: updates can leak, participants can attack the system and heterogeneity can hide bias. Pair it with strong privacy techniques, security controls, fairness testing and clear agreements. The FAQs below cover common questions.
Frequently Asked Questions
What is federated learning?
Training a shared model across devices or organizations without centralizing raw data.
Who developed it?
It was popularized by Google researchers around 2016.
How does it work?
Participants train locally and share model updates that a server combines.
What is cross-device federated learning?
Training across many phones or sensors with small local datasets.
What is cross-silo federated learning?
Training across a few organizations, such as hospitals or banks.
Is federated learning private?
It improves privacy, but updates can leak, so extra safeguards are needed.
What is secure aggregation?
A method that lets a server combine updates without seeing individual ones.
How does differential privacy help?
It adds noise so individual records have limited influence on shared updates.
What is a gradient inversion attack?
An attack that reconstructs training data from shared gradients.
What is model poisoning?
A participant sends malicious updates to harm or manipulate the model.
Can federated learning reduce bias?
It can broaden data diversity, but it can also hide bias without subgroup testing.
What is non-IID data?
Data that is distributed differently across participants.
Does it meet GDPR requirements automatically?
No, lawful basis, purpose limits and other duties still apply.
Which industries use it?
Healthcare, finance, telecom, consumer technology and industry.
What are its main drawbacks?
Communication cost, complexity, heterogeneity and security risks.
How do you audit a federated model?
Through documentation, participant-level testing, logs and monitoring.
What should a collaboration agreement include?
Data ownership, permitted use, security, liability, model ownership and exit terms.
What is vertical federated learning?
Parties hold different features about the same individuals and train jointly.
Is it cheaper than centralized training?
Not always. Coordination and communication can add cost.
Where should teams begin?
With a clear threat model, legal review and a small pilot.
Related Articles
View All
Artificial Intelligence
Certified Responsible AI Expert™: Course Overview, Learning Outcomes and Who Should Enrol
Explore the Certified Responsible AI Expert™ course, including its curriculum, key learning outcomes, and intended audience. Discover the skills and knowledge learners can gain in AI ethics, governance, risk management, compliance, and responsible AI implementation.
Artificial Intelligence
How to Become a Responsible AI Expert: Skills, Learning Path and Certification
Learn how to become a Responsible AI expert with a clear learning path covering essential skills, relevant qualifications, and industry certifications. Explore how to build expertise in AI ethics, governance, risk management, compliance, and responsible AI practices.
Artificial Intelligence
Responsible AI in Government and Public Services: Opportunities and Risks
Explore how responsible AI can improve government operations and public services through faster processes, better resource allocation, and data-driven decisions. Learn about the opportunities, risks, and ethical challenges of using AI while protecting citizen privacy, ensuring fairness, and maintaining transparency and accountability.
Trending Articles
The Role of Blockchain in Ethical AI Development
How blockchain technology is being used to promote transparency and accountability in artificial intelligence systems.
AWS Career Roadmap
A step-by-step guide to building a successful career in Amazon Web Services cloud computing.
Top 5 DeFi Platforms
Explore the leading decentralized finance platforms and what makes each one unique in the evolving DeFi landscape.