

What Is Jev Typesafe's AI Model and How Does It Work?
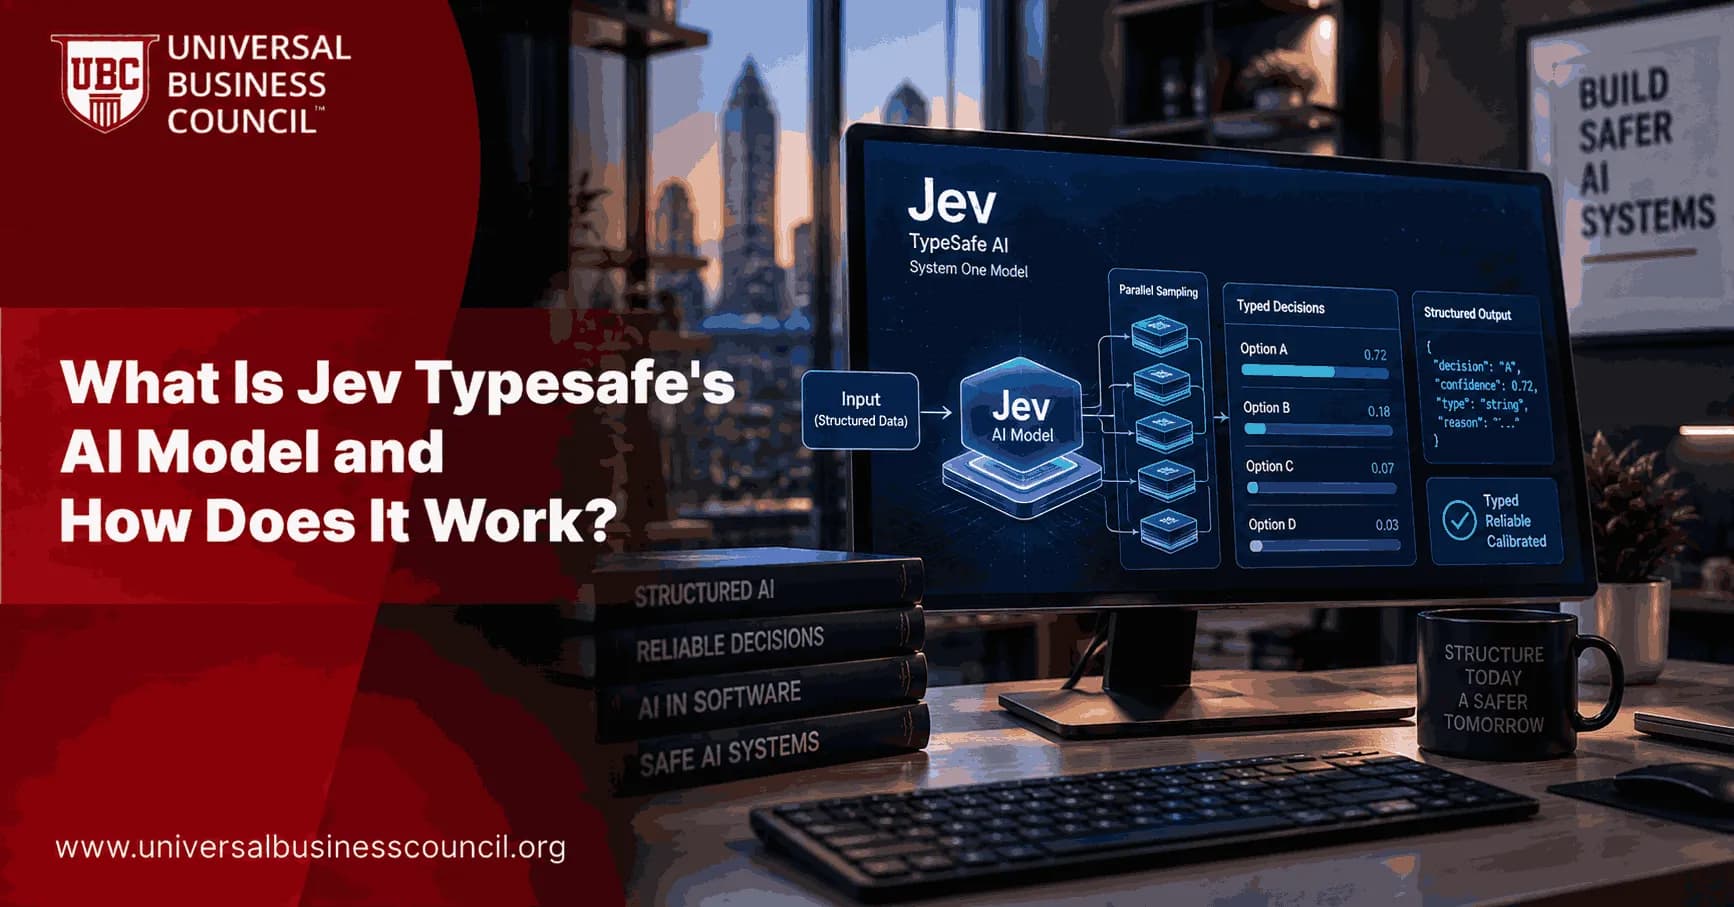
Jev is the first release from a company betting that not every AI problem needs a chatbot. Launched in early access on September 15, 2026 by a San Francisco startup called TypeSafe AI or typesafe.ai, Jev skips text generation entirely and instead returns typed, structured decisions that software can use directly, without any parsing or interpretation step in between. This guide explains exactly what Jev is, how it works under the hood, and where it genuinely fits, written clearly enough for a beginner while offering real technical depth for developers evaluating it. For teams trying to explain a technical shift like this clearly to stakeholders, a Marketing Certification helps translate unfamiliar technical concepts into a business case people outside engineering can actually follow.
Who Built Jev, and Why
TypeSafe AI was founded in 2024 by Diogo Almeida, alongside co-founders Erik Gafni and Sasha Sheng. Almeida previously worked as a researcher at OpenAI, where he was one of the co-inventors of reinforcement learning from human feedback, the training technique that helped turn early language models into the conversational systems behind tools like ChatGPT. After roughly two years operating in stealth, TypeSafe emerged publicly with forty million dollars in funding and Jev as its first product.

The underlying motivation behind Jev is straightforward once explained. Large language models are built to generate text for humans to read. When a piece of software needs a structured judgment instead, such as a classification, a routing decision, or an approval score, developers typically have to coerce a text-generation system into producing something structured, then parse that text back into a format their code can actually use. TypeSafe designed Jev specifically to remove that mismatch, building a model that returns structured answers directly rather than prose that needs interpreting afterward. Making sense of a genuinely new AI architecture like this becomes considerably easier with solid foundational knowledge already in place. Exploring Artificial Intelligence Certifications provides exactly that kind of grounding, helping both technical and non-technical readers evaluate new model categories on their actual merits rather than marketing claims alone.
What Makes Jev Different From a Chatbot
TypeSafe describes Jev as the first model in a new category it calls System One models, borrowing the term from psychologist Daniel Kahneman's description of fast, intuitive human thinking. Where a large language model works through problems by generating a sequence of tokens one at a time, often reasoning out loud in the process, Jev takes an entirely different approach. It does not chat, does not write code, does not summarize or translate, and has no conversational interface at all.
Instead, Jev accepts a block of state, which can be a JSON object or something as simple as a plain text description such as a customer complaint, along with a set of typed questions about that state. It evaluates every question in a single parallel pass and returns typed answers with calibrated probability scores attached, rather than a written explanation a developer would need to interpret or extract information from afterward.
How Jev Actually Works
State and Typed Questions
The basic workflow starts with a developer sending Jev a piece of state, essentially the raw information relevant to a decision, paired with specific questions framed using Jev's typed question system. TypeSafe's documentation emphasizes that each question should ask one specific, well-scoped thing, with more complex logic broken down into smaller atomic questions that get recombined afterward within the developer's own application code, rather than handed to the model as one large reasoning task.
The Three Question Types
Jev supports three question primitives. A Choice question returns a selection among predefined options along with a probability for each. A Score question returns a numeric value with an associated confidence level. A third primitive, referred to in TypeSafe's documentation, returns a probability distribution rather than a single fixed answer. Together, these primitives are meant to cover the kind of narrow, well-defined judgments that traditionally relied on brittle, hand-written business rules, what TypeSafe describes as replacing hard-coded if-statements with something considerably smarter and more adaptive.
Reinforcement Learning for Calibrated Decisions
Jev's training relies on a method TypeSafe calls Reinforcement Learning for Calibrated Decisions, or RLCD. The company positions this as a third distinct post-training approach, alongside reinforcement learning from human feedback, which shaped conversational chatbots, and reinforcement learning from verifiable rewards, which produced stronger reasoning models for tasks like mathematics at the cost of slower, more expensive inference. RLCD, according to TypeSafe, trains the model specifically to produce well-calibrated probabilities on narrow, structured tasks, meaning a stated confidence score should genuinely reflect how likely that answer is to be correct. It is worth noting that TypeSafe has described this approach only at a high level publicly, without releasing model weights or a detailed research paper that would let outside researchers independently reproduce these specific results.
Speed and Cost Claims
The numbers TypeSafe has published around Jev are genuinely striking, though they come entirely from the company's own internal testing rather than independent, third-party verification. TypeSafe reports Jev responding in roughly seventy to five hundred milliseconds, with one demo showing a response in just over a tenth of a second, compared to more than eight and a half seconds for a competing frontier language model handling the same kind of structured task.
On pricing, TypeSafe lists input costs at four cents and two-tenths of a cent per million tokens, an unusually low figure compared to typical frontier model pricing. Combined, the company claims Jev runs somewhere between forty and two hundred times faster, and forty to four hundred times cheaper, than comparable large language models on the narrow, structured tasks it targets, using TypeSafe's own benchmark workflows and its own structured-output comparison wrapper for competing models. TypeSafe itself has acknowledged these specific comparisons may not generalize cleanly to every use case, which is a reasonable caveat given how much benchmark results can shift depending on exactly how a comparison gets constructed.
What Jev Is Good At vs. What It Cannot Do
Jev's intended use cases center on classification, routing, scoring, and branching, essentially the narrow, repeatable decisions that many production systems currently handle through hard-coded logic or simpler traditional machine learning classifiers. On an internal four-workflow benchmark, TypeSafe reports Jev achieving roughly sixty-eight percent accuracy, putting it in the same general range as mid-tier conversational language models, but at a fraction of the latency and cost for these specific narrow tasks.
What Jev explicitly cannot do matters just as much as what it can. It generates no free-form text, writes no code, produces no summaries or translations, and accepts no image input. There is no chat interface of any kind. Anything requiring a written explanation, creative output, or open-ended reasoning still needs a traditional language model behind it. TypeSafe frames this narrowness as a deliberate tradeoff, describing Jev as giving up string generation entirely in exchange for speed, cost efficiency, and structural reliability on the specific tasks it does handle.
Real-World Demo: Controlling a Doom Bot
To showcase Jev's speed in a tangible way, TypeSafe demonstrated the model controlling a bot playing the classic video game Doom, making roughly ten decisions per second at an estimated operating cost of about seven dollars per hour. Rather than processing raw game visuals, the bot received a structured, text-based representation of the game state, which Jev then evaluated to make rapid movement and combat decisions in real time. This demo served less as a claim that Jev is built for gaming specifically, and more as a concrete illustration of how quickly and cheaply it can make repeated, structured decisions under time pressure.
Emerging Applications of Generative AI
While Jev itself sits outside traditional text generation, the broader generative AI landscape it emerged alongside continues expanding into genuinely creative territory as well. One emerging application is AI microdrama, where generative AI helps bring serialized stories, characters, and fictional worlds to life.
This contrast highlights an important point about the current AI landscape: rather than converging toward one universal model type, the field increasingly seems to be splitting into specialized categories, generative systems built for open-ended creative and conversational work on one side, and narrower, structured decision systems like Jev built for speed and reliability inside production software on the other. Professionals looking to build broader technical literacy across this expanding landscape benefit from a general Tech Certification, which helps make sense of how these increasingly specialized model categories fit together within the wider technology ecosystem.
How Jev Compares to Traditional Large Language Models
The clearest way to understand Jev is through direct contrast with the conversational models most people already know. Large language models take sequential text input and generate text output token by token, making them flexible enough to handle writing, coding, translation, and open-ended reasoning, but comparatively slow and expensive for narrow, repeated structured decisions. Jev takes structured program state as input and returns typed answers with calibrated probabilities in one parallel pass, sacrificing that broad flexibility entirely in exchange for speed, cost efficiency, and freedom from parsing or hallucination risk on the specific narrow tasks it targets.
Neither approach replaces the other. A production system might reasonably use a conventional language model to draft customer-facing text while relying on a System One model like Jev to make the rapid, repeated classification or routing decisions happening behind the scenes within that same application.
Should Businesses Use Jev Today?
Given that Jev remains in early access, available currently through a waitlist rather than open signup, most organizations are still in an evaluation rather than production-adoption phase. TypeSafe itself has framed this stage explicitly as an invitation for early users to identify both genuinely useful decisions and failure cases, acknowledging that the real test is whether Jev's narrowness proves dependable enough for production software, rather than simply impressive within a controlled benchmark.
Organizations with high-volume, narrow, repeatable decision points already embedded in their systems, particularly ones currently handled through brittle hand-written rules or expensive language model calls, represent the most natural early candidates for testing Jev directly against their own real workloads rather than relying solely on TypeSafe's published figures.
Learning Path for Understanding New AI Architectures
As genuinely new model categories like System One models continue emerging, building a broad, adaptable technical foundation matters more than memorizing any single company's specific product. Professionals interested in tracking how frontier AI architecture continues diversifying, including how specialized systems increasingly complement rather than replace traditional generative models, can explore Deep Tech Certification options to build the kind of forward-looking technical perspective that helps evaluate genuinely new categories like Jev on their actual merits.
Conclusion
Jev represents a genuinely different approach to applying AI inside software, trading text generation entirely for fast, typed, structured decisions that code can consume directly without parsing or interpretation. Backed by claims of dramatically lower latency and cost compared to conventional language models, though currently verified only through TypeSafe's own internal testing, Jev's real test will come as early-access developers evaluate whether its narrow, schema-bound design proves genuinely dependable inside real production systems rather than just fast within a controlled demo.
Frequently Asked Questions
1. What is Jev?
Jev is an AI model released by TypeSafe AI that returns typed, structured decisions instead of generating text, designed for use directly inside software systems.
2. Who created Jev?
Jev was created by TypeSafe AI, a startup founded in 2024 by former OpenAI researcher Diogo Almeida along with co-founders Erik Gafni and Sasha Sheng.
3. When was Jev released?
Jev launched in early access on September 15, 2026.
4. What is a System One model?
A System One model is TypeSafe's term for a new category of AI model that returns typed probabilistic decisions instead of generated text.
5. Can Jev write text or generate code?
No, Jev cannot generate text, write code, summarize, translate, or accept image input, and it has no chat interface of any kind.
6. How does Jev process information?
Jev takes a block of state, such as a JSON object or text description, along with typed questions, and returns structured answers in a single parallel pass.
7. What are Jev's three question types?
Jev supports Choice questions, Score questions, and a third primitive returning a probability distribution rather than a single fixed answer.
8. What training method does Jev use?
Jev was trained using a method TypeSafe calls Reinforcement Learning for Calibrated Decisions, or RLCD.
9. How fast is Jev compared to traditional language models?
TypeSafe claims Jev responds in roughly seventy to five hundred milliseconds, significantly faster than typical conversational language models on similar tasks.
10. How much does Jev cost to use?
TypeSafe lists input pricing at approximately four cents per million tokens, according to the company's published rates.
11. Are TypeSafe's speed and cost claims independently verified?
No, these figures currently come from TypeSafe's own internal testing rather than independent, third-party verification.
12. What tasks is Jev designed for?
Jev targets classification, routing, scoring, and branching decisions, essentially structured judgments that software can use directly.
13. What accuracy does Jev achieve on TypeSafe's benchmarks?
TypeSafe reports roughly sixty-eight percent accuracy on its internal four-workflow benchmark, comparable to mid-tier conversational language models.
14. Did TypeSafe demonstrate Jev in a real-world use case?
Yes, TypeSafe demonstrated Jev controlling a bot playing Doom, making roughly ten structured decisions per second based on text-based game state.
15. Is Jev publicly available to everyone?
No, Jev is currently available only through early access, requiring developers to join a waitlist rather than sign up directly.
16. Has TypeSafe published a research paper on Jev's architecture?
No, TypeSafe has described its approach only at a high level publicly, without releasing model weights or a detailed reproducible research paper.
17. How does Jev differ from traditional machine learning classifiers?
Jev is a frontier model trained specifically to produce calibrated, typed probabilistic decisions, positioned as more flexible than narrowly trained traditional classifiers.
18. Can Jev replace a conversational AI model entirely?
No, Jev is designed to complement rather than replace conversational models, since it cannot handle tasks requiring text generation or open-ended reasoning.
19. What industries might benefit most from a model like Jev?
Industries with high-volume, repeatable structured decisions, such as customer service routing, fraud scoring, and workflow automation, represent natural early use cases.
20. What should businesses do before adopting Jev in production?
Businesses should test Jev directly against their own real workloads during early access, since TypeSafe itself acknowledges that dependability, not just speed, remains the key open question.
Related Articles
View All
Artificial Intelligence
How Does Recursive Self-Improvement Work in AI?
Recursive self-improvement in AI describes a process where an AI system improves parts of its own capabilities and then uses those gains to make further improvements over repeated cycles.

Artificial Intelligence
OpenAI launches ChatGPT Work: What the new work-focused ChatGPT means for teams
OpenAI launches ChatGPT Work signals a shift from chatbot to workplace AI layer, with team workspaces, agents, apps, company search, and governance needs.

Artificial Intelligence
Recursive Self-Improvement in AI: Benefits, Risks, Challenges, and Future Impact
Explore recursive self-improvement in AI, including its potential benefits, technical challenges, safety risks, and possible impact on the future of artificial intelligence.
Trending Articles
The Role of Blockchain in Ethical AI Development
How blockchain technology is being used to promote transparency and accountability in artificial intelligence systems.
AWS Career Roadmap
A step-by-step guide to building a successful career in Amazon Web Services cloud computing.
Top 5 DeFi Platforms
Explore the leading decentralized finance platforms and what makes each one unique in the evolving DeFi landscape.